

Baseten
NexusAi Summary: Baseten is a production inference platform that serves custom, open, and fine-tuned models with sub-second latency, cross-cloud scaling, and developer-first APIs. It combines optimized runtimes, embeddings inference, and compound AI orchestration for performance-critical AI applications.
NexusAi Overview
Teams develop or bring models, then deploy them to Baseten’s inference stack where runtime optimizations, hardware-aware autoscaling, and caching reduce latency and cost. The platform exposes simple APIs and SDKs for endpoint creation, versioning, and rollout.
Core capabilities
Baseten is aimed at engineering teams building latency-critical products — search and retrieval systems, real-time transcription, voice agents, image generation workflows, and domain-specific LLMs. It suits startups and enterprises that require strict SLAs, hardware-aware autoscaling, and the ability to serve custom or open-source models without rearchitecting their inference pipeline.
- Deploy any open-source or proprietary model as a production endpoint with APIs.
- Serve high-throughput embeddings with BEI for faster vector search and retrieval.
- Run real-time transcription and low‑TTFB text‑to‑speech for voice applications.
- Scale across clouds with single‑tenant and self‑hosted deployment options.
- Optimize throughput with kernel research, caching, and hardware-aware autoscaling.
Performance highlights
Customer perspective
Begin by creating an account or requesting a demo, then register models via the Baseten console or CLI and deploy them as endpoints. Use the Loops SDK to train and promote models from experiment to production. Configure deployment options for Baseten Cloud or self-hosted VPCs, set autoscaling and caching policies, and integrate with your CI/CD and logging pipelines. Documentation, SDKs, and sample integrations provide step-by-step guides and API references for fast production rollout.
NexusAi: “I want the best possible experience for our users, but also for our company. Baseten has hands down provided both.” — Nathan Sobo, Co‑Founder, Zed Industries
Getting started
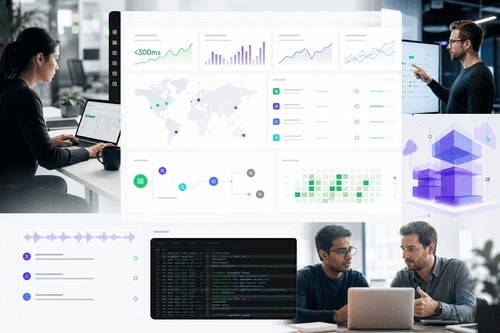
Baseten’s strength is combining measurable runtime gains with operational primitives and deployment flexibility. It reduces the engineering lift of productionizing models while delivering predictable latency, improved GPU efficiency, and options for isolated single‑tenant deployments—making it a pragmatic choice for teams prioritising inference reliability and performance.
Open the tool and review its core product experience.
Create your account or access your existing workspace.
Use your own task to judge speed, quality, and fit.
Check similar AI tools before making a final decision.
Baseten
Baseten builds inference infrastructure and developer tools that let engineering teams deploy and operate models at scale. The company focuses on runtime research, embeddings acceleration, and operational support for latency-sensitive, production AI applications.
Baseten is a dedicated inference platform purpose-built to deploy and operate AI models at scale. It pairs inference-optimized infrastructure, kernel-level performance research, and developer tooling so teams can serve open-source, proprietary, or fine-tuned models with predictable latency and high throughput. The stack includes Baseten Embeddings Inference (BEI), optimized LLM runtimes, real-time audio pipelines for low-TTFB speech use cases, and orchestration for compound AI (Baseten Chains). Deployments run in Baseten Cloud, self-hosted VPCs, or hybrid configurations with single-tenant clusters available for isolation. For engineering teams the product reduces cold starts, improves GPU utilization, and provides APIs and SDKs to integrate model endpoints, caching, autoscaling, and monitoring into production systems.
Visit Baseten
Comments (0)
No Comments Found