


Harness2
NexusAi Summary: Harness2 is a plug-and-play framework for recursive agent harnessing that refines agent harnesses without changing model weights. It iteratively proposes, probes, and composes harness edits to improve agent behavior in open-world tasks.
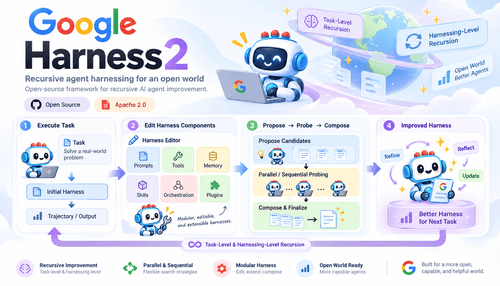
NexusAi Overview
In practice, Harness2 frames harness design as an iterative search: propose candidate edits, execute probes to surface behavioral differences, and compose a refined harness that adopts effective changes. The loop runs without ground-truth labels and preserves lessons to accelerate future tasks.
Core capabilities
The framework targets engineers and researchers who design agent systems, benchmark harness strategies, or need reproducible harness improvements without re-training models. Typical users refine tool loops for code, legal, or office workflows, compare executor behaviors, and scale experiment budgets to measure marginal gains across tasks and domains.
- Propose–Probe–Compose edits harness components through contrastive execution evidence.
- Parallel and sequential recursion modes balance exploration breadth and refinement depth.
- Supports OpenCode and Codex executors for real and sandboxed code execution.
- Persists adopted harnesses and lessons to guide future task refinements automatically.
- Integrates with JobBench, LAB, and WorkBuddy-Bench for standardized evaluation.
Practical trends
Representative quote
Install on Linux with Python 3.12, create an isolated environment, and install repository dependencies. For model-backed runs configure credentials and model IDs in an environment file, install optional benchmark dependencies, then run the harness2 demo or benchmark commands to produce reproducible runs. The toolkit provides flags for parallel versus sequential recursion, task selection preview, and judge/report stages to keep evaluation consistent.
NexusAi: Harness2 turns harness engineering into a measurable, reusable experiment loop without changing model weights.
Getting started
Harness2 is best used where iterative harness improvement and reproducible evaluation matter: benchmark-driven research, engineering teams refining tool loops, and cases where model weights must remain fixed. Its combination of contrastive editing, persistent lessons, and executor flexibility differentiates it from ad hoc prompt tuning.
Open the tool and review its core product experience.
Create your account or access your existing workspace.
Use your own task to judge speed, quality, and fit.
Check similar AI tools before making a final decision.
Harness2
Google Research maintains experimental tooling and infrastructure for foundational model research. Their teams publish reproducible frameworks that bridge research methods and engineering practices for practitioner adoption.
Harness2 (Harness²) provides a reproducible, model-agnostic system for improving agent harnesses—prompts, tools, memory, skills, and orchestration—through recursion rather than weight updates. At task time it runs a Propose–Probe–Compose loop to generate candidate harness edits, probe their effects on the same task, and compose a refined harness from behavioral contrasts. Across parallel and sequential recursion modes, the framework retains adopted harnesses and evidence to guide future refinement. The release supports OpenCode and Codex executors and integrates benchmark tooling for JobBench, LAB, and WorkBuddy-Bench. Designed for research and engineering workflows, Harness2 balances deterministic editors, real execution, and optional model-backed evaluations so teams can iterate harness design, measure gains, and resume experiments reproducibly.
Visit Harness2
Comments (0)
No Comments Found