


NVIDIA RTX Spark
NexusAi Summary: Compact RTX hardware and software for on‑device AI agents, creators, and developers. RTX Spark pairs Blackwell-class RTX GPUs with Grace CPUs and unified memory to run large models locally and accelerate 3D, video, and inference workflows.
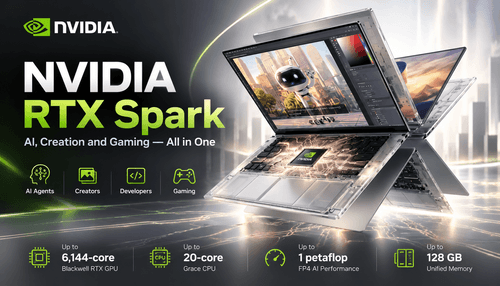
NexusAi Overview
In practice, RTX Spark lets developers iterate locally: train or fine‑tune models on-device, run multi-component agents, and preview GPU-accelerated 3D scenes without cloud latency. The unified memory reduces model fragmentation and enables larger context windows within a single machine.
Capabilities and technical profile
RTX Spark is best suited to engineers and technical buyers who need local model execution and low-latency agents: AI researchers iterating on model behavior, developers building private agents, creators who require offline rendering and high-quality video encoding, and small teams that want desktop-grade inference without a cloud bill. It also serves operations teams managing edge deployments that require secure, local processing.
- Runs large model inference locally with up to 128 GB unified memory.
- Supports native CUDA, TensorRT, and NVFP4 for accelerated FP4 inference.
- Encodes and decodes HEVC, H.264, and AV1 for fast media workflows.
- Hosts personal AI agents that execute workflows while preserving local data.
- Seamlessly scales code to cloud NVIDIA GPUs without code changes.
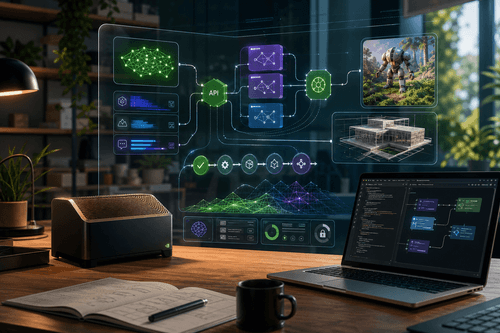
Practical trends and use cases
On-device agent workflows
Begin with a Windows 11 RTX Spark system, install NVIDIA Studio or Game Ready drivers, and set up the CUDA toolkit. Use TensorRT and NVFP4 optimizations for inference; NGC provides prebuilt containers and models for rapid prototyping. Developers can run the same binaries on larger NVIDIA servers without code changes, enabling a consistent workflow from local testing to cloud scale. Documentation and SDKs on NVIDIA developer portals explain driver setup, performance tuning, and media codec usage for optimal throughput.
NexusAi: Run models locally for instant iteration and predictable costs while keeping sensitive data on your machine.
Getting started and developer path
RTX Spark narrows the gap between laptop convenience and datacenter capability by combining efficient hardware with the CUDA ecosystem. It reduces operational costs for continuous agent workloads, accelerates creative pipelines, and preserves data locality for privacy-sensitive applications. For teams that need immediate model iteration and predictable on-device performance, RTX Spark offers a compact, developer-first platform.
Open the tool and review its core product experience.
Create your account or access your existing workspace.
Use your own task to judge speed, quality, and fit.
Check similar AI tools before making a final decision.
NVIDIA RTX Spark
NVIDIA builds hardware and software stacks that accelerate AI, graphics, and simulation. The company’s expertise spans GPUs, CUDA tooling, drivers, and developer platforms designed to move workloads from local devices to data centers consistently.
RTX Spark is a compact platform that brings datacenter-class AI capability to slim laptops and small desktops. It integrates NVIDIA Blackwell RTX GPUs with Grace CPUs and up to 128 GB of unified memory to enable local inference of large models, agent execution, and GPU-accelerated creative workflows. The stack supports CUDA, TensorRT, and NVFP4 optimizations, enabling high-throughput FP4 inference, native on-device development, and seamless scaling to cloud NVIDIA GPUs when needed. RTX Spark targets workflows that benefit from low latency, data locality, and offline operation: interactive model development, real-time agent orchestration, on-device video and 3D rendering, and uninterrupted round-the-clock inference on compact desktop systems. It is designed to reduce iteration time, eliminate per-prompt charges for local workloads, and provide a consistent development-to-deployment path using the same CUDA-compatible toolchain found across NVIDIA’s ecosystem.
Visit NVIDIA RTX Spark
Comments (0)
No Comments Found