


Prism
NexusAi Summary: Prism Bonsai 2 27B is a ternary-quantized large language model delivering near full-precision quality at a fraction of memory, compute, and energy. Built on Qwen 3.8 27B, it enables capable local agents on commodity hardware with 5.9 GB weights.

NexusAi Overview
Teams use Bonsai 2 by loading the 5.9 GB weights locally, wiring standard prompting and tool-use scaffolding, then benchmarking against their latency and power budgets. The model’s small memory footprint unlocks parallelism and real-time interactivity on GPUs, consumer PCs, and embedded edge systems that larger models overload.
What It Does
Bonsai 2 suits engineers building edge or desktop agents, researchers exploring quantization trade-offs, and product teams constrained by cost, privacy, or unreliable connectivity. It’s a strong fit for local coding copilots, on-prem knowledge tools, interactive UI assistants, and embedded multimodal experiences. Operators evaluating TCO can use Bonsai 2 to increase concurrency or reduce accelerator count while holding quality nearly constant.
- Maintains near full-precision quality while compressing to a compact 5.9 GB.
- Enables agentic coding and long-horizon tool use on consumer and edge hardware.
- Delivers higher tokens per second under constrained memory bandwidth and power.
- Supports multimodal reasoning with responsive, low-latency interaction across local deployments.
- Improves concurrency and throughput, reducing accelerator count for cost-sensitive serving.
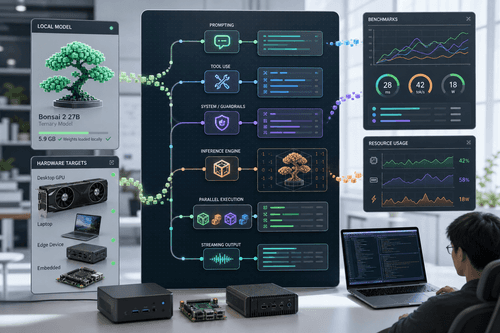
Highlights
Who Should Use It
Start by reviewing the docs and whitepaper to understand the evaluation methodology and supported variants (1-bit and ternary across model sizes). Download the Bonsai 2 27B weights and try the public demo to validate latency, memory residency, and throughput on your target hardware. Bonsai Studio offers a guided environment for hands-on experiments, including prompt iteration and quick benchmarking. Integrate the model into existing inference stacks or lightweight runtimes, then layer tools, retrieval, and safety rules as required by your application. Measure quality against representative workloads before rolling out to production.
NexusAi: Intelligence density matters: deliver more capability per bit, not just more bits.
How to Get Started
Prism’s focus on intelligence per bit makes Bonsai 2 27B unusually practical: 9x smaller memory, up to 8x faster, and roughly 5x less energy with minimal quality loss. The result is a frontier-class experience on local devices, suitable for agent workflows, multimodal reasoning, and cost-sensitive deployment. If you need speed and efficiency without shipping data to the cloud, Bonsai is built for you.
Open the tool and review its core product experience.
Create your account or access your existing workspace.
Use your own task to judge speed, quality, and fit.
Check similar AI tools before making a final decision.
Prism
Prism ML is a research-driven company focused on efficient AI systems. Drawing on quantization breakthroughs from Caltech collaborators, the team builds ultra-dense models and tooling that maximize capability per bit. Their work targets edge, consumer, and datacenter deployments where cost, latency, and energy dominate.
Prism Bonsai 2 27B is the company’s most capable release of its ultra-dense ternary model family, engineered to deliver 98.2% of full-precision performance while shrinking the footprint 9x, boosting throughput up to 8x, and cutting energy by roughly 5x. At just 5.9 GB, the model brings agentic coding, multimodal reasoning, and long-horizon tool use to local devices that previously could not host frontier-scale systems. Built on Qwen 3.8 27B, Bonsai 2 pairs compression with carefully balanced training to preserve reasoning quality, then validates results across an internal intelligence density framework that normalizes accuracy by model size. The outcome is a practical foundation for edge and datacenter deployments when cost, latency, or power are binding constraints. Downloadable weights, docs, benchmarks, and a public demo make it straightforward to evaluate real-world fit without heavy infrastructure.
Visit Prism
Comments (0)
No Comments Found