


Reka
NexusAi Summary: Reka builds omni-modal models and a low-latency cloud engineered for real-time perception in physical environments, combining egocentric video, trajectory data, distilled models, and quantized runtimes for deployment at 24 frames per second.
NexusAi Overview
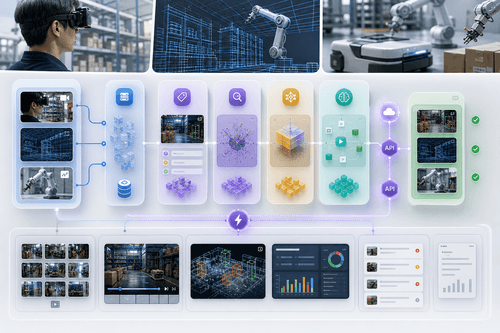
Reka’s workflow ingests synchronized egocentric video, world-model footage, and robotics trajectories, then applies annotation, retrieval, and distilled inference to produce labeled events, tracked objects, and action recommendations. Outputs are searchable clips, structured scene understanding, and short-latency alerts tied to operational reports.
Capabilities
Typical users include robotics teams, vision engineers, operational safety teams, and research groups that need deterministic low-latency perception pipelines. Reka fits projects where continuous video streams, object-centric tracking, and temporal clipping feed downstream automation, analytics, or compliance systems requiring explainable, time-aligned evidence.
- Distilled omni models deliver near-teacher quality with much lower runtime cost.
- Quantized weights reduce model size to fit existing edge and cloud hardware.
- Video infra tags, clips, and indexes footage for rapid incident retrieval.
- Large-scale RL tunes models directly against operational tasks, not benchmarks.
- APIs expose inference, search, and clip retrieval for integration into workflows.
Real-time omnidata inference at production scale
Who it's for
Teams begin by provisioning Reka Cloud, uploading representative video or trajectory datasets, and running the default tagging pipeline to generate indexed clips. Comprehensive API documentation covers model inference endpoints, clip retrieval, and annotation exports; SDKs and example clients streamline integration. Onboarding emphasizes a small validation set and task-specific RL tuning to align the distilled model with the customer’s operational objectives.
NexusAi: Making omnidata models run inside a single frame is the product.
Getting started
Reka’s strength is the integration of data, model engineering, and real-time infrastructure: curated egocentric datasets, task-aligned RL, and aggressive compression yield models that actually fit operational budgets. That engineering trade-off—maintaining accuracy while enabling deployability—is the primary differentiator for teams moving perception research into live systems.
Open the tool and review its core product experience.
Create your account or access your existing workspace.
Use your own task to judge speed, quality, and fit.
Check similar AI tools before making a final decision.
Reka
Reka.ai is a research and engineering lab focused on foundational intelligence for the physical world. The team specialises in omni-modal models, video infrastructure, and efficient runtimes aimed at production deployments in robotics and operations.
Reka develops omni models and infrastructure designed to run real-time perception and reasoning across video, audio, and trajectory data. The platform emphasizes inference at 24 frames per second on existing hardware by using distillation, aggressive quantization, and task-specific RL to preserve teacher-model quality while shrinking runtime. Reka Cloud provides APIs and scalable video infrastructure for tagging, clipping, search, and judgement aggregation. The stack pairs curated egocentric and world-model footage with annotation pipelines and large-scale RL to optimize models against operational tasks rather than benchmark proxies. Reka targets teams building automation, safety monitoring, and robotics perception where latency, accuracy, and deployability determine product feasibility.
Visit Reka
Comments (0)
No Comments Found