MorningAI’s Multi-Model Agents Add GPT-6 Sol, GPT-6 Luna, Claude Opus 5.5, and Grok 4.7—with Sanity CMS Publishing Built In
MorningAI now lets teams pick GPT-6 Sol, GPT-6 Luna, Claude Opus 5.5, or Grok 4.7 inside a single Agent, and push Sanity CMS content from draft to scheduled publish with approvals. The update consolidates model choice, content ops, and task tracking into one workflow.
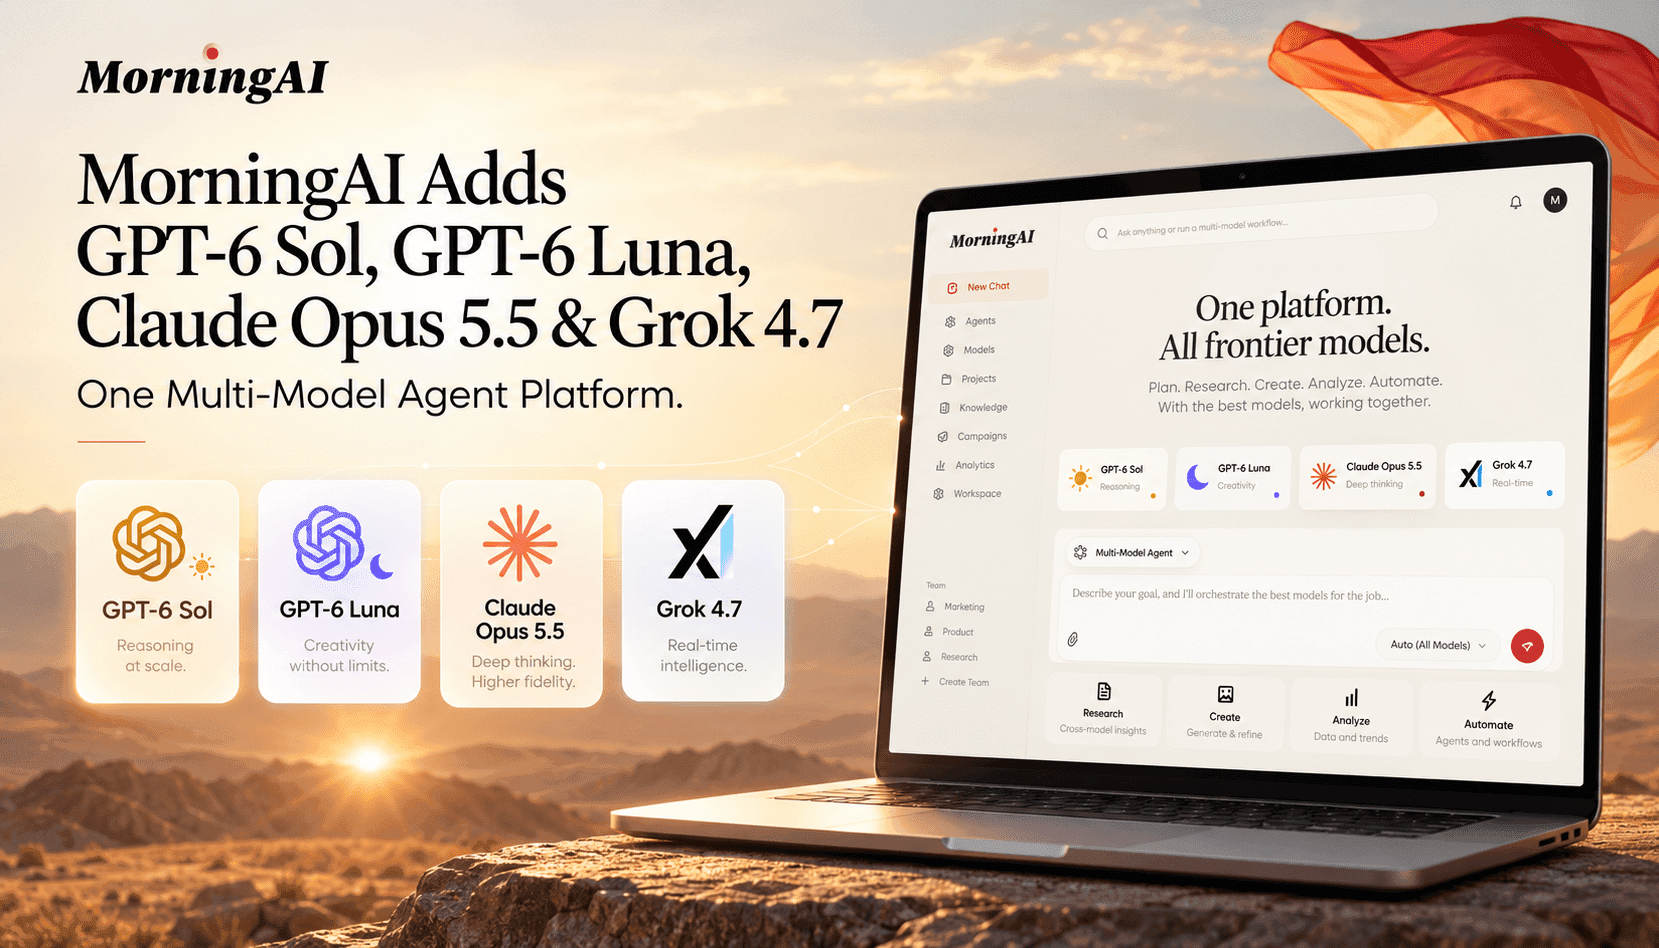
AI BriefMorningAI folds four frontier models—GPT-6 Sol, GPT-6 Luna, Claude Opus 5.5, and Grok 4.7—into one Agent workspace while enabling end-to-end Sanity CMS execution (draft, review, schedule, publish) with approvals. The practical upshot: teams can map jobs to the right model inside a shared composer, keep legacy choices available, and compress content ops into a governed, auditable flow. Expect faster turnarounds and clearer ownership, provided you tune approvals, rate limits, and cost controls. For leaders, this update signals a steady shift from “model picks in chat” to durable, multi-model workflows spanning content, tasks, and scheduling—less tool-juggling, more accountable throughput.
MorningAI’s latest release puts four flagship models—GPT-6 Sol, GPT-6 Luna, Claude Opus 5.5, and Grok 4.7—into a single Agent composer, while keeping previous-generation options within reach. That matters because most teams don’t need a one-size-fits-all model; they need a reliable way to assign the right engine per task without context loss or workflow friction. The platform remembers your selection, so you can standardize choices for recurring work while still switching on the fly when speed, budget, or depth changes.
The second pillar is end-to-end Sanity CMS handling. Agents can draft, revise, add or swap images, schedule, and publish—wrapped in approval gates. Instead of pushing content between tools, writers and operators stay in one thread to move from ideation to scheduled post. This is less about novelty and more about dependable throughput: fewer handoffs, clearer status, and easier audits when leadership asks what shipped, why, and with which model backing the work.
For operators, the big gain is control. You can align model choice to intent (reasoning vs. velocity), codify review steps in approvals, and manage timing in Calendar. The new Tasks area ties into this rhythm so teams can coordinate who owns what without leaving the Agent. The remaining work is governance: define which jobs qualify for which model, tune cost ceilings, and make post-publication checks routine. Done right, the release converts scattershot chat experiments into durable, team-level content operations.
Key Takeaways
Route Tasks to the Right Model
Standardize defaults: Sol/Opus for complex reasoning, Luna for quick drafts, Grok for exploratory ideation. Measure edit deltas and reassign models where quality or speed lags.
Make CMS Publishing Governed
Use approvals, required fields, and Calendar to enforce brand, SEO, and accessibility standards before anything ships from Sanity.
Instrument Cost and Quality
Set per-model budgets, track draft-to-approval time, and review outputs quarterly to catch model drift or routing mismatches early.
What Changed: One Agent, Four Frontier Models
MorningAI now surfaces GPT-6 Sol, GPT-6 Luna, Claude Opus 5.5, and Grok 4.7 directly in the Agent composer, with previous-generation models preserved under a separate list. Users pick per task without reconfiguring workspaces, and MorningAI remembers the choice until you change it. This trims set-up time and reduces accidental context resets.
Practically, teams can designate Sol or Opus for complex planning and analysis, use Luna for quick-turn drafts, and tap Grok when latency or alternative reasoning styles help. Centralizing selection also makes it easier to standardize model policies and compare outputs across families without forcing separate tools or parallel chat threads.
Why It Matters: Match Model to Job, Not Vice Versa
The release aligns with how high-performing teams already work: they allocate deep reasoning to premium models and everyday tasks to faster, cheaper ones. Embedding this decision inside the Agent composer means fewer ad hoc guidelines and more consistent execution. It also raises the bar on evaluation—A/B outputs across models on the same brief to set baselines by task type.
Expect measurable gains in cycle time and cost control if you institutionalize defaults. For example, set Luna for first-pass drafts under 600 words, Sol/Opus for multi-step research and policy-heavy content, and Grok for exploratory ideation. Over time, compare quality and editing deltas to refine the routing playbook and retire underperforming defaults.
CMS End-to-End: Draft, Review, Schedule, Publish in Sanity
Agents can now take Sanity documents from idea to scheduled publish with approvals woven into the flow. In practice, a marketer can request a draft, iterate tone and structure, generate or swap imagery, and schedule a release—without leaving the conversation. The same editor opens for any document type your Sanity project defines, extending beyond blog posts to customer stories or custom content types.
Governance is the difference-maker. Use approval steps to enforce brand, legal, and accessibility checks; keep auditability by capturing changes, timestamps, and the model used. The Calendar view lets teams visualize queued posts alongside other scheduled work, which reduces collisions and clarifies what is shipping this week versus next.
Implementation Playbook: Settings, Roles, and Rollout
Start with a routing matrix: define which content types use which default model and why. Lock in cost ceilings per workspace, and enforce a two-step approval for SEO or regulatory-sensitive posts. In Sanity, confirm required fields for title, description, alt text, and schema-specific validations so agents can’t schedule incomplete content.
Operationalize measurement. Track draft-to-approval time, edit counts per model, and scheduled-to-published slippage. Use Tasks to assign owners for draft, SEO review, and final sign-off. Run a two-week pilot on three post types (announcement, how-to, story), compare outputs across models, then codify defaults and exceptions in team playbooks.
Risks and Controls: Brand, Drift, and Cost Discipline
Multi-model freedom can fragment voice and inflate cost if left unchecked. Mitigate with tone templates, style linters, and a mandatory human edit for tier-one assets. Monitor model updates that shift behavior; schedule quarterly evaluations to ensure the routing matrix still holds and previous-generation models haven’t silently degraded outcomes.
Control blast radius in CMS: restrict publish permissions, maintain environment parity (staging vs. production), and enable rollback patterns. For cost, set per-model budgets and alerting on spike conditions. Finally, establish a fallback: if scheduling or image generation fails, tasks should auto-assign to a human owner with context attached.
Frequently Asked Questions
How should teams decide when to use Sol, Luna, Opus 5.5, or Grok 4.7?
Create a routing matrix by task: use Sol or Opus for multi-step analysis and policy-heavy content, Luna for short or iterative drafts, and Grok for ideation or when latency matters. Validate with A/B reviews on the same brief and promote the model with fewer edits at equal or lower cost.
What governance steps keep agent-led Sanity publishing safe?
Require approvals for brand/legal, enforce required metadata (titles, alt text, canonical), restrict publish rights, and use staging previews. Log model choice, changes, and timestamps; if an approval is skipped or an image fails, auto-create a Task with context for human review.
How do we manage spend as more models enter the workspace?
Set per-workspace and per-model budgets with alerts, default cheaper models for routine tasks, and reserve premium models for complex work. Track edit counts and draft-to-approval times; if a premium model doesn’t reduce edits or time-to-ship, downgrade its default assignment.