

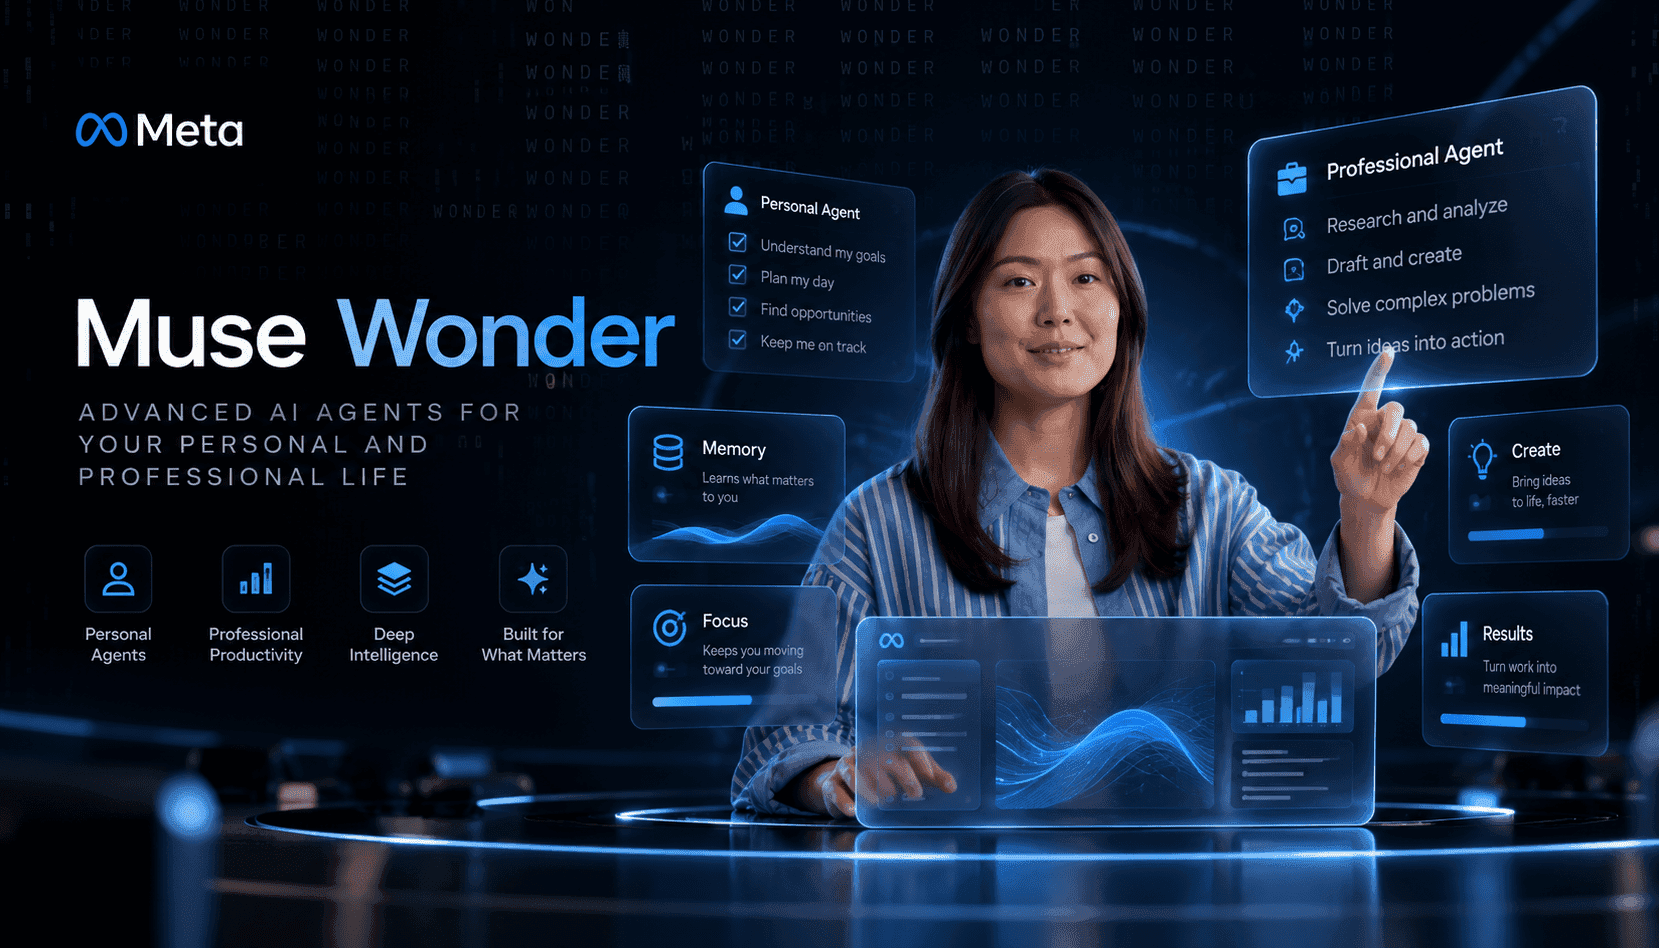
Meta’s announcement of Muse Wonder and Muse Wonder Full is more than a raw capability upgrade: it’s a clear productization of agent-first primitives. Active Memory lets the model carry forward task-relevant facts, user preferences, and prior decisions across conversations, reducing repetition and accelerating multi-step workflows. Active Focus complements memory by enabling goal-directed persistence — retrying failed approaches, proposing alternatives, and sequencing subtasks toward completion while asking for clarifications at decision points that matter.
From a developer perspective, Meta positions Muse Wonder as accessible today via the Meta Model API and Muse Code, while Muse Wonder Full arrives for Muse Code subscribers. That split matters: Muse Wonder provides broad access for integrating higher-level reasoning into apps, whereas Wonder Full appears tailored to more demanding, possibly costlier workflows that require peak accuracy across law, finance, and health use cases. Builders will need to rethink state management — opting to rely on native Active Memory primitives rather than ad hoc external context stores in many cases.
Strategically, Muse Wonder changes Meta’s competitive posture. It narrows the gap to OpenAI’s GPT-6, Anthropic’s Claude, and Google’s Gemini on long-horizon agent tasks by embedding memory and focus as first-class capabilities rather than integrations. That raises immediate questions about benchmark comparability, pricing, and ecosystem lock-in: teams choosing Meta gain integrated agent tools, but must evaluate how memory retention, permissioning, and portability fit enterprise compliance and multi-cloud strategies.