

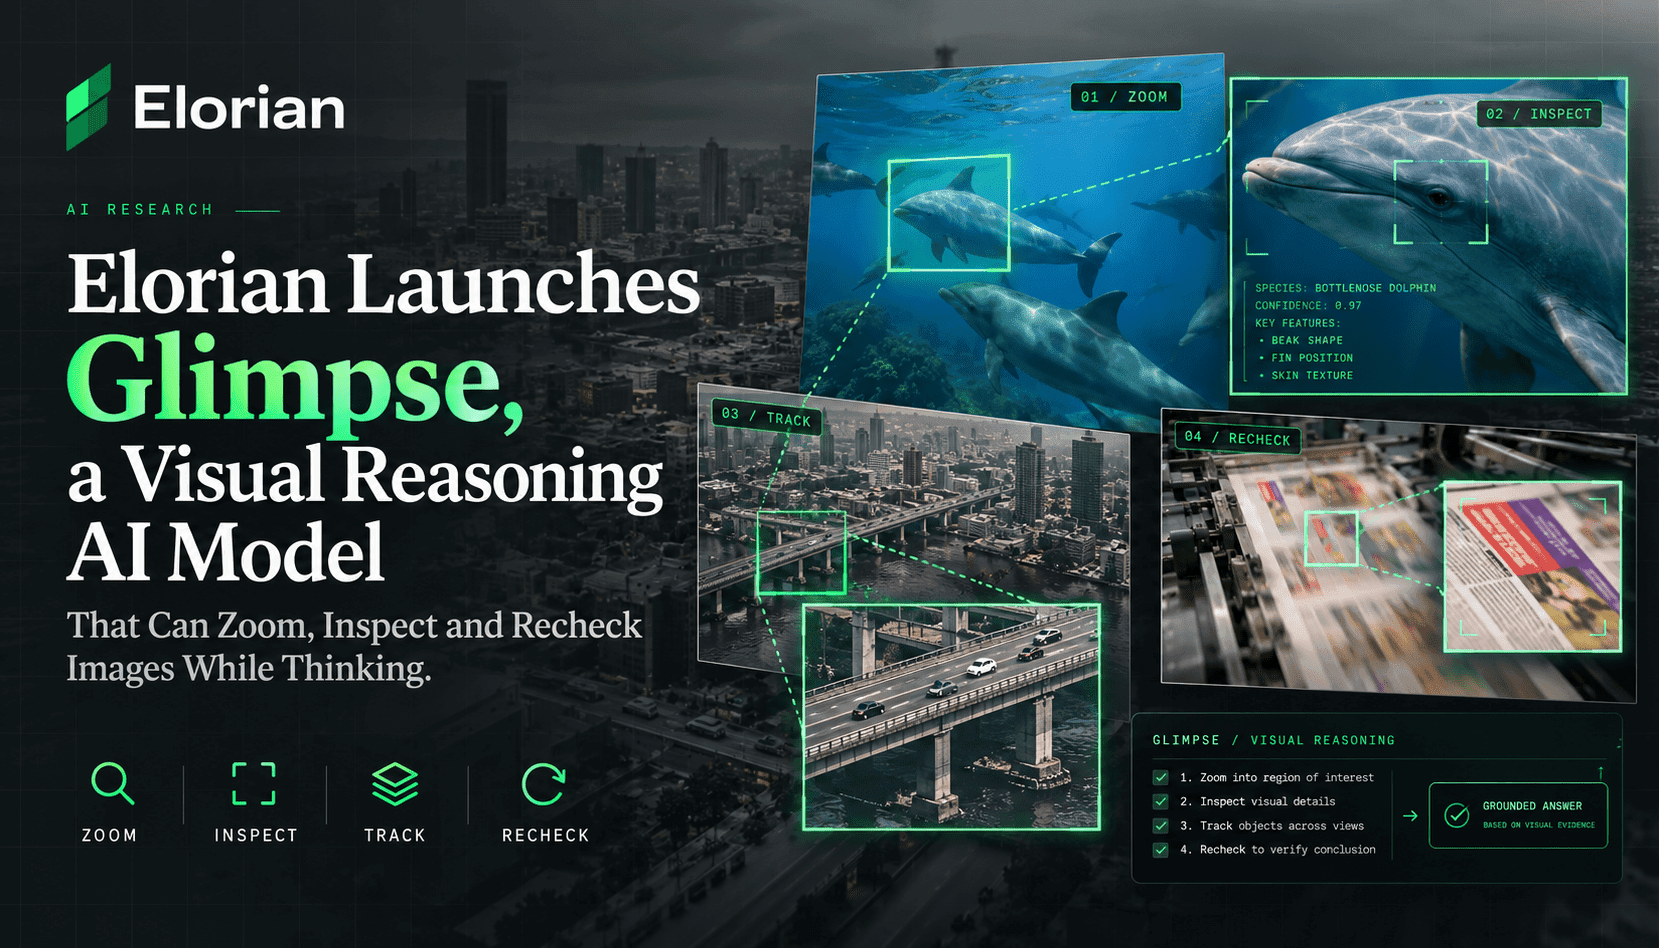
Elorian’s Glimpse marks a deliberate shift in how multimodal systems treat visual input. Rather than compressing an image or video into a single latent token sequence and reasoning from that frozen summary, Glimpse preserves a manipulable ‘visual scratch space’ the model can revisit during multi-step thinking. Practically, that means the model can crop to a region, request denser frame samples, track an object’s pixels across time, or run short code snippets that produce intermediate visual artifacts. The result is less reliance on brittle, single-pass perception and a higher tolerance for ambiguous or dynamic scenes.
From a systems perspective the key engineering trade is compute and token budget versus grounded accuracy. Glimpse’s design intentionally spends extra inference effort to reexamine the evidence where a single-pass approach would guess from memory. Elorian reports that this dense review yields stronger performance on tasks that require identity preservation, temporal reasoning and precise counts — and that those gains can match or exceed much larger frontier models on selected benchmarks. For teams, that suggests Glimpse is most compelling where visual fidelity, traceability and stepwise verification matter more than raw throughput.
Adopting Glimpse requires product and research tradeoffs: you gain a model that reasons with visual evidence, but you pay with more complex orchestration—managing sampled frames, scratch artifacts and potentially higher token cost per session. Elorian’s published prices are materially lower per-token than several frontier LLMs, but their own notes confirm the model uses more tokens when it thinks thoroughly. In short, Glimpse promises a better evidence trail and fewer perceptual failures for certain tasks, but teams must measure end-to-end latency, cost per decision and integration complexity to justify migration.
For buyers and builders, the practical takeaway is straightforward: treat Glimpse as a tool for workflows where rechecking visual evidence is a feature, not a bug. Use it for robot verification, lab chart interpretation, manufacturing QA and dense video captioning where false positives or lost identities are expensive. For high-volume, low-stakes tagging or where latency is critical, a conventional single-pass multimodal model may still be preferable until further token-efficiency gains arrive.